Encode
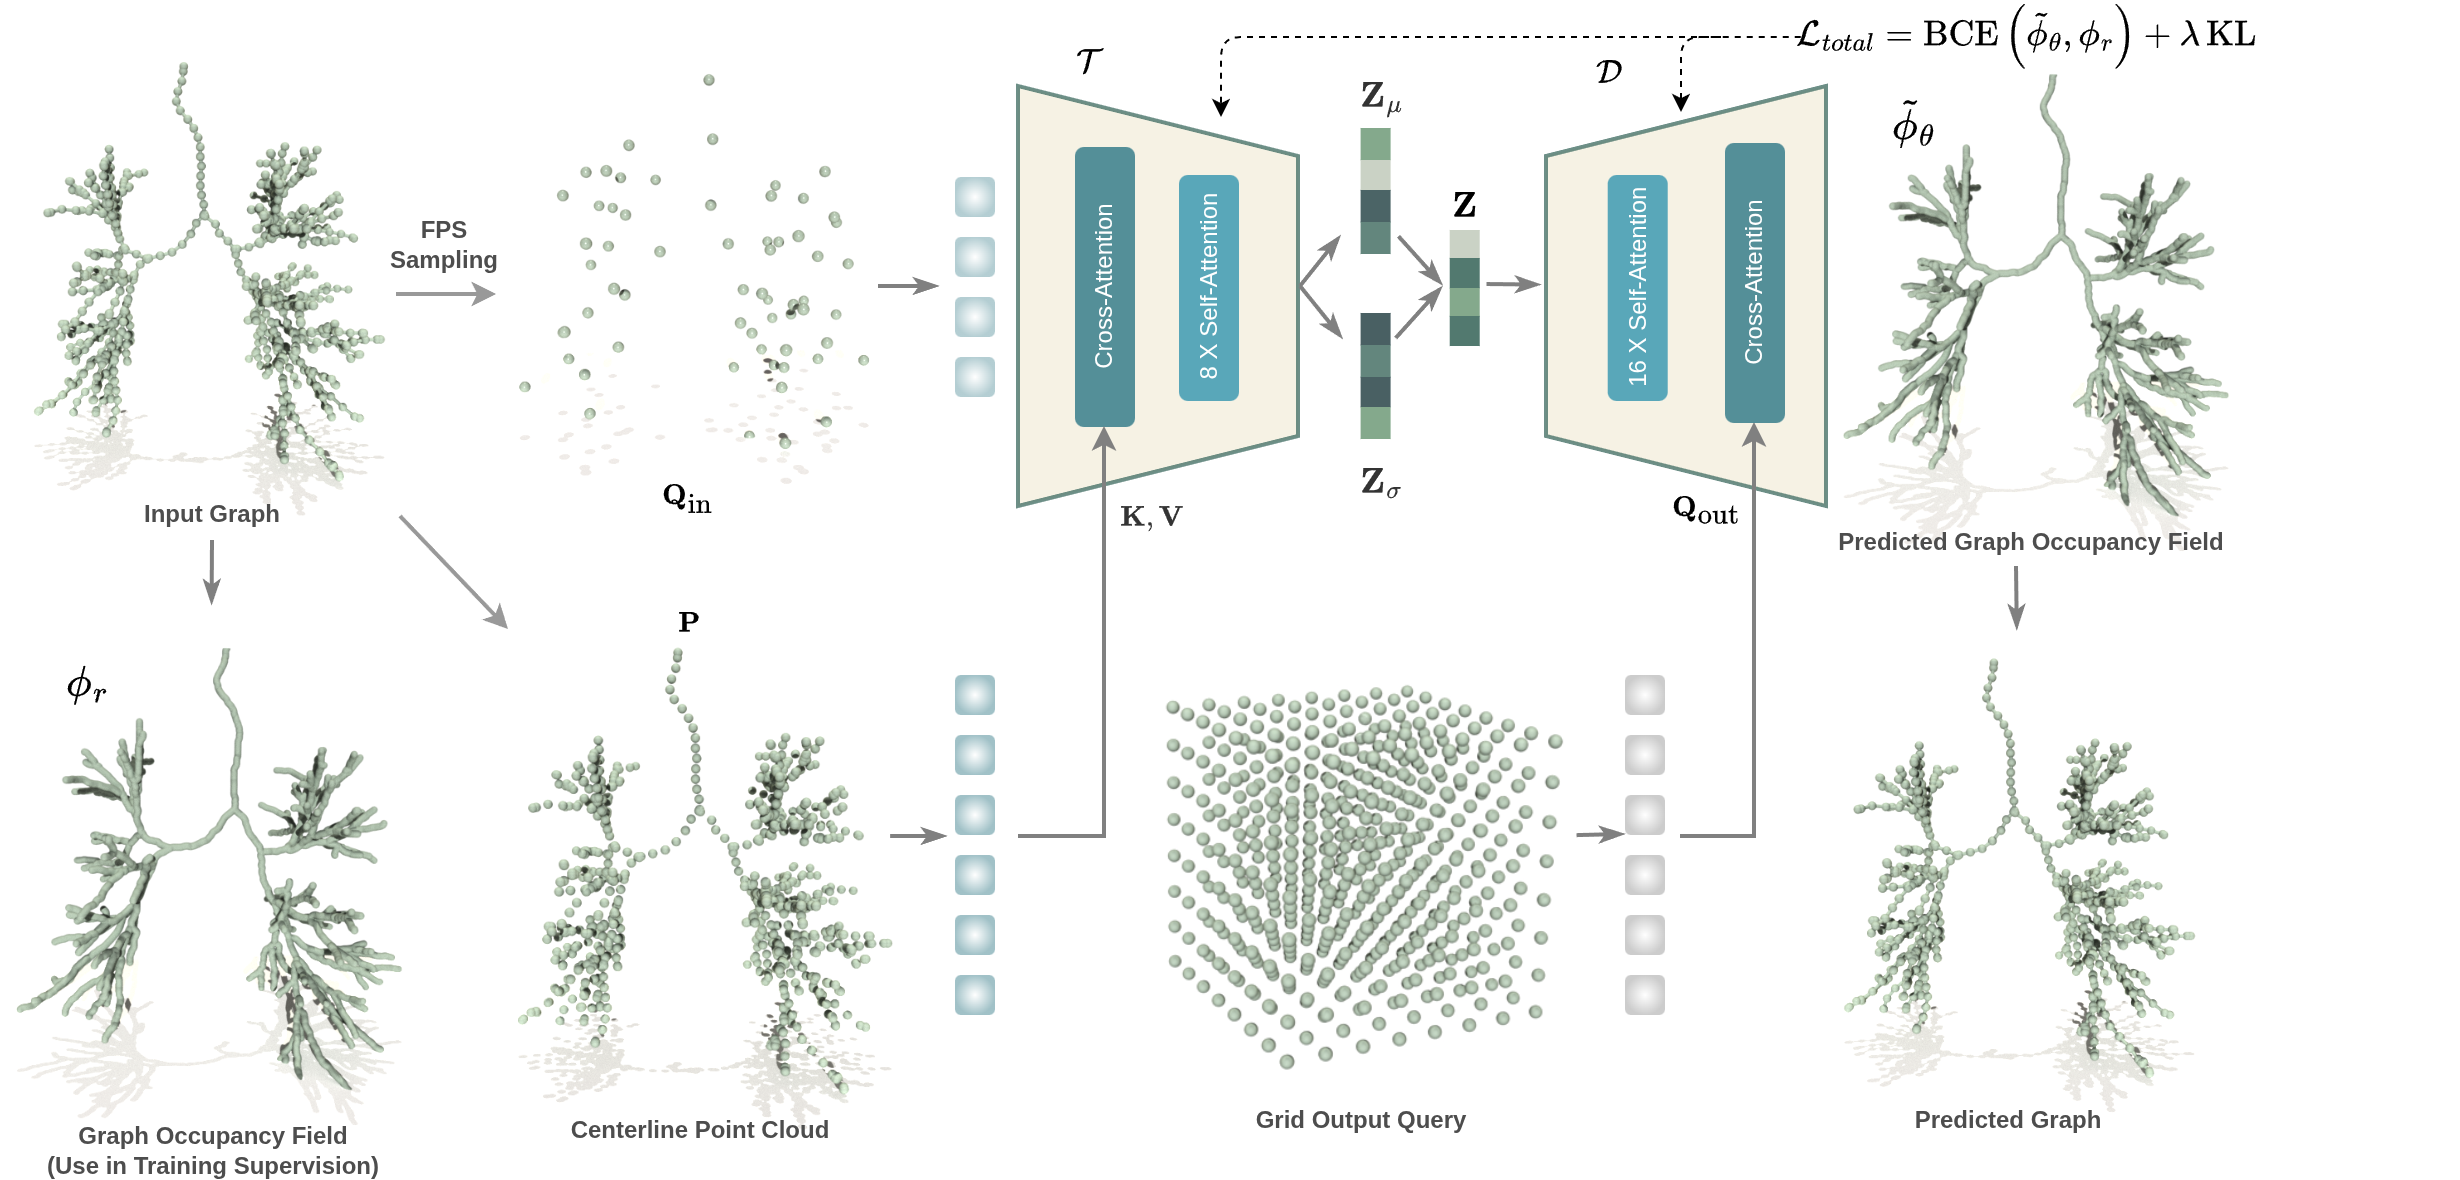
An implicit-function autoencoder transforms a centerline graph with pseudo-radius information into a compact set of learned tokens.
ECCV 2026 Spotlight
Tokenizing Vessel-like 3D Biomedical Graph Representations for Reconstruction and Generation
VesselTok method overview · Original figure ↗
Overview
Vessel-like structures form intricate spatial networks. VesselTok compresses their geometry into learned latent tokens that support accurate reconstruction and generative modeling without requiring a heavily simplified branch-level representation.
Approach
An implicit-function autoencoder transforms a centerline graph with pseudo-radius information into a compact set of learned tokens.
The learned tokens are decoded into an occupancy field, from which a vessel-like graph can be recovered.
Generative models operate in the latent space: diffusion supports sampling, and flow matching supports conditional infilling.
Research directions
Represent complex vascular and airway geometry using compact learned tokens.
Learn distributions over three-dimensional vessel-like structures in the latent space.
Use conditional generative modeling for structural infilling of partial observations.
Resources
The public repository contains implementations of the autoencoder, latent generative models, evaluation, and experiment configurations. Check the repository for installation instructions and model/data availability.
Reference
@inproceedings{prabhakar2026vesseltok,
  title = {VesselTok: Tokenizing Vessel-like 3D Biomedical Graph Representations for Reconstruction and Generation},
  author = {Prabhakar, Chinmay and Wittmann, Bastian and Amiranashvili, Tamaz and B{\"u}schl, Paul and de la Rosa, Ezequiel and McGinnis, Julian and Wiestler, Benedikt and Menze, Bjoern and Shit, Suprosanna},
  booktitle = {Proceedings of the European Conference on Computer Vision (ECCV)},
  year = {2026},
  note = {arXiv:2603.18797}
}
Please check the final proceedings citation information when available.