Masked views
Create randomly masked views of a 2D image or 3D volume and encode the visible patches.
MIDL 2023 · PMLR Vol. 227
Improving Vision Transformer Autoencoder for Self-supervised Medical Image Representations
Presented at MIDL 2023; indexed in the PMLR 227 proceedings listing.
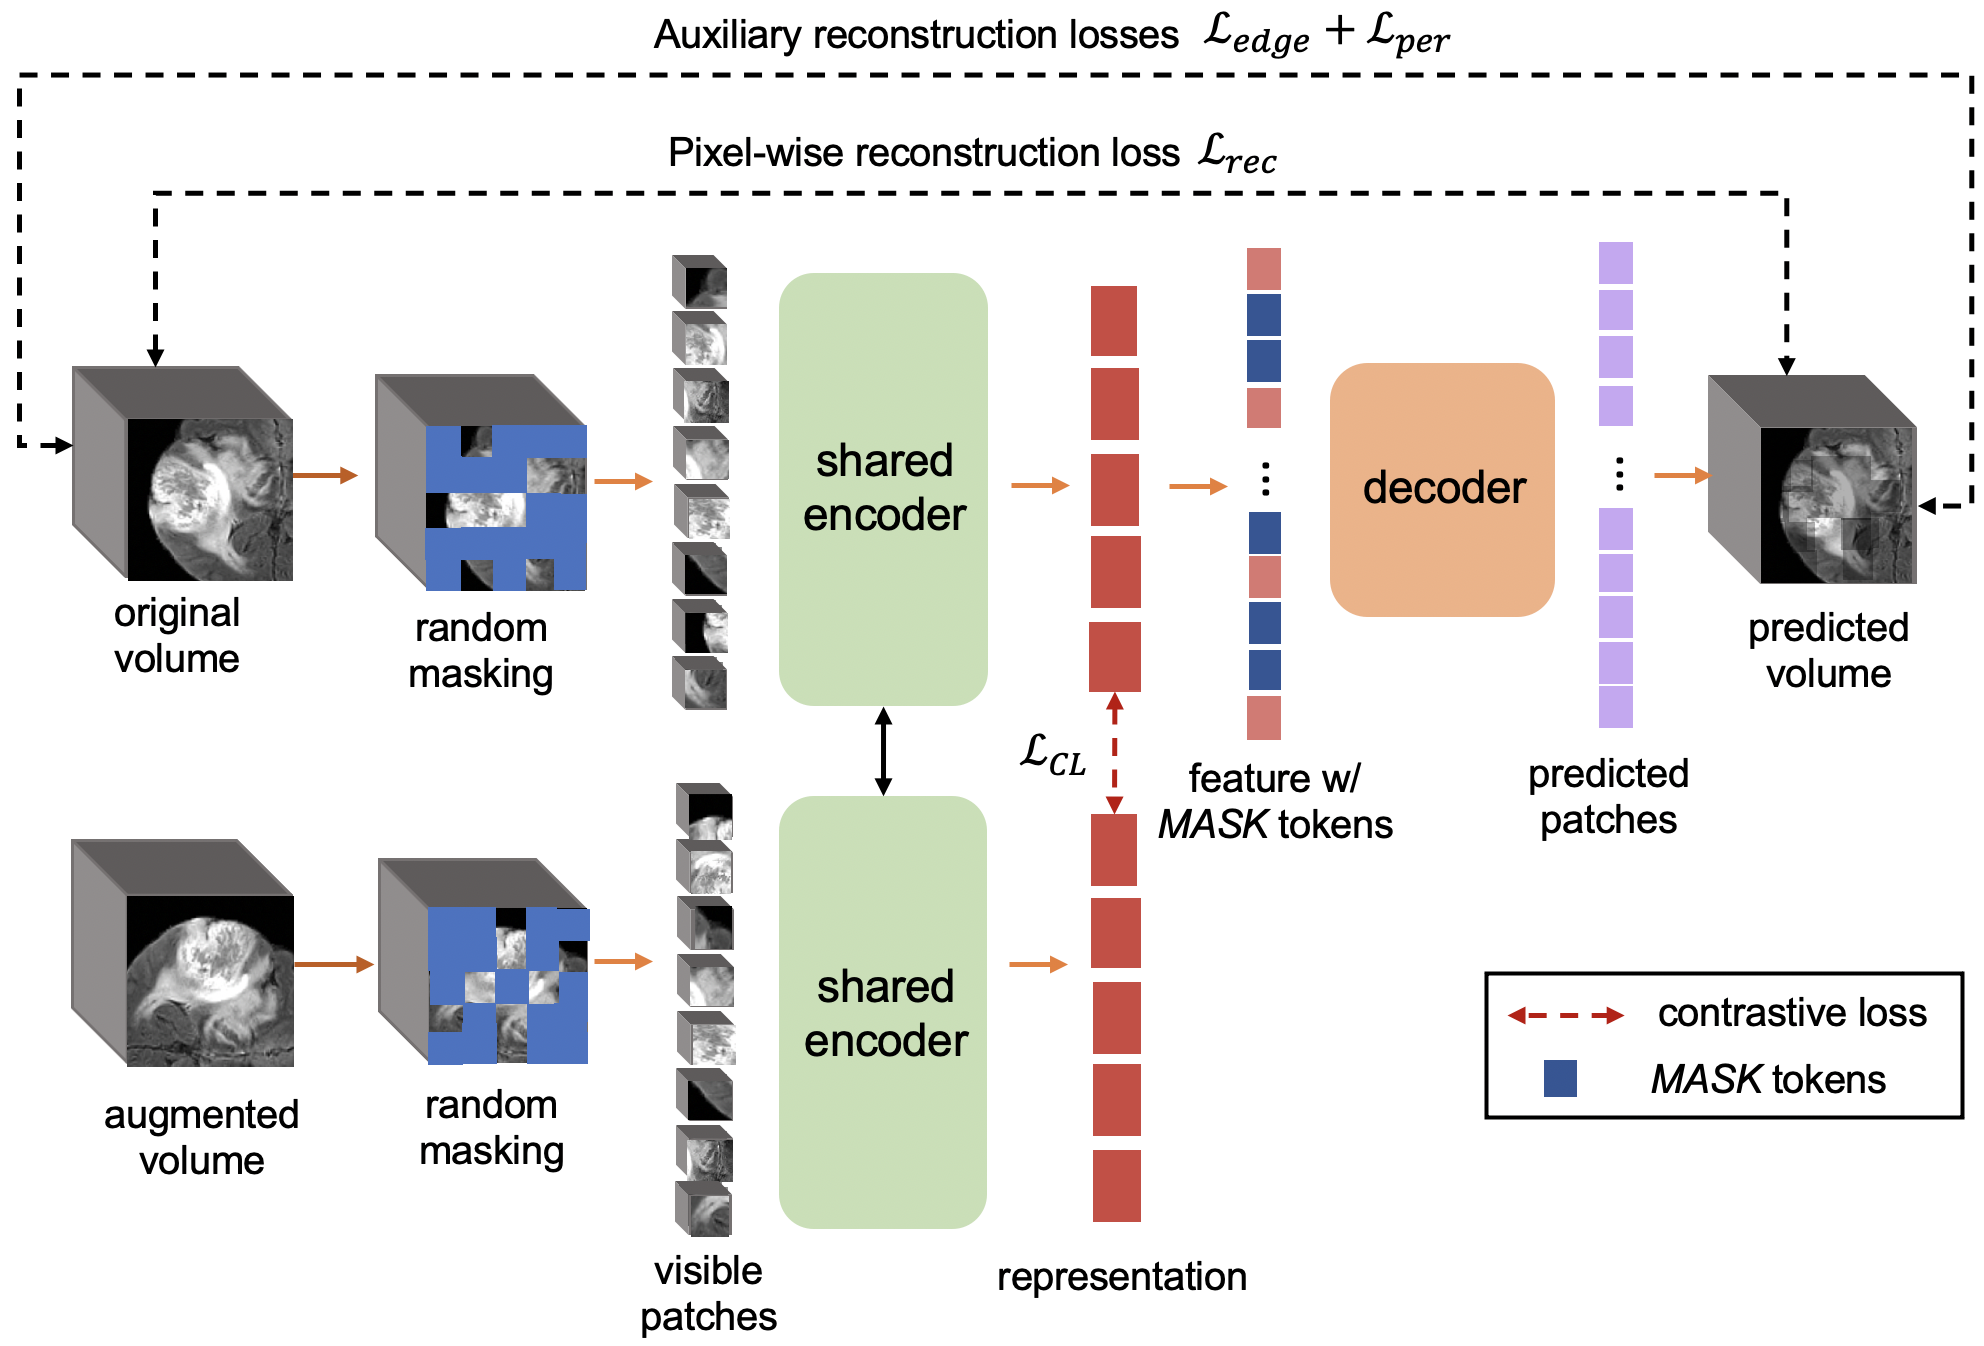
ViT-AE++ Figure 1 (original paper architecture).
Overview
Masked vision transformer autoencoders learn image representations without manual annotation. ViT-AE++ improves this approach for 2D and 3D medical images by complementing pixel reconstruction with structure-aware auxiliary objectives and representation alignment across two masked views.
Approach
Create randomly masked views of a 2D image or 3D volume and encode the visible patches.
Reconstruct the input with pixel-level and auxiliary perceptual and edge-aware losses.
Use representations from two masked views to encourage informative, consistent features.
Research directions
Learn useful image features before task-specific annotation or fine-tuning.
Extend the masked-autoencoding strategy to volumetric medical images.
Jointly improve structural reconstruction and agreement between masked-view embeddings.
Resources
Read the published paper for the full methodology, experimental evaluation, and original figures. The public GitHub repository includes the research code.
Reference
@InProceedings{pmlr-v227-prabhakar24b,
  title = {{ViT-AE++}: Improving Vision Transformer Autoencoder for Self-supervised Medical Image Representations},
  author = {Prabhakar, Chinmay and Li, Hongwei and Yang, Jiancheng and Shit, Suprosanna and Wiestler, Benedikt and Menze, Bjoern},
  booktitle = {Medical Imaging with Deep Learning},
  pages = {666--679},
  year = {2024},
  volume = {227},
  series = {Proceedings of Machine Learning Research},
  publisher = {PMLR},
  url = {https://proceedings.mlr.press/v227/prabhakar24b.html}
}
Use the citation details from the publisher if the publication record is updated.